Top
Best
New

Posted by Philpax 7 hours ago

Redesigning source control at Anthropic(www.anthropic.com)
429 points | 420 commentspage 3
jgbuddy 2 hours ago|
> Anthropic uses Claude to write software far more than almost any other company

Who's beating Anthropic here lol

preommr 5 hours ago||
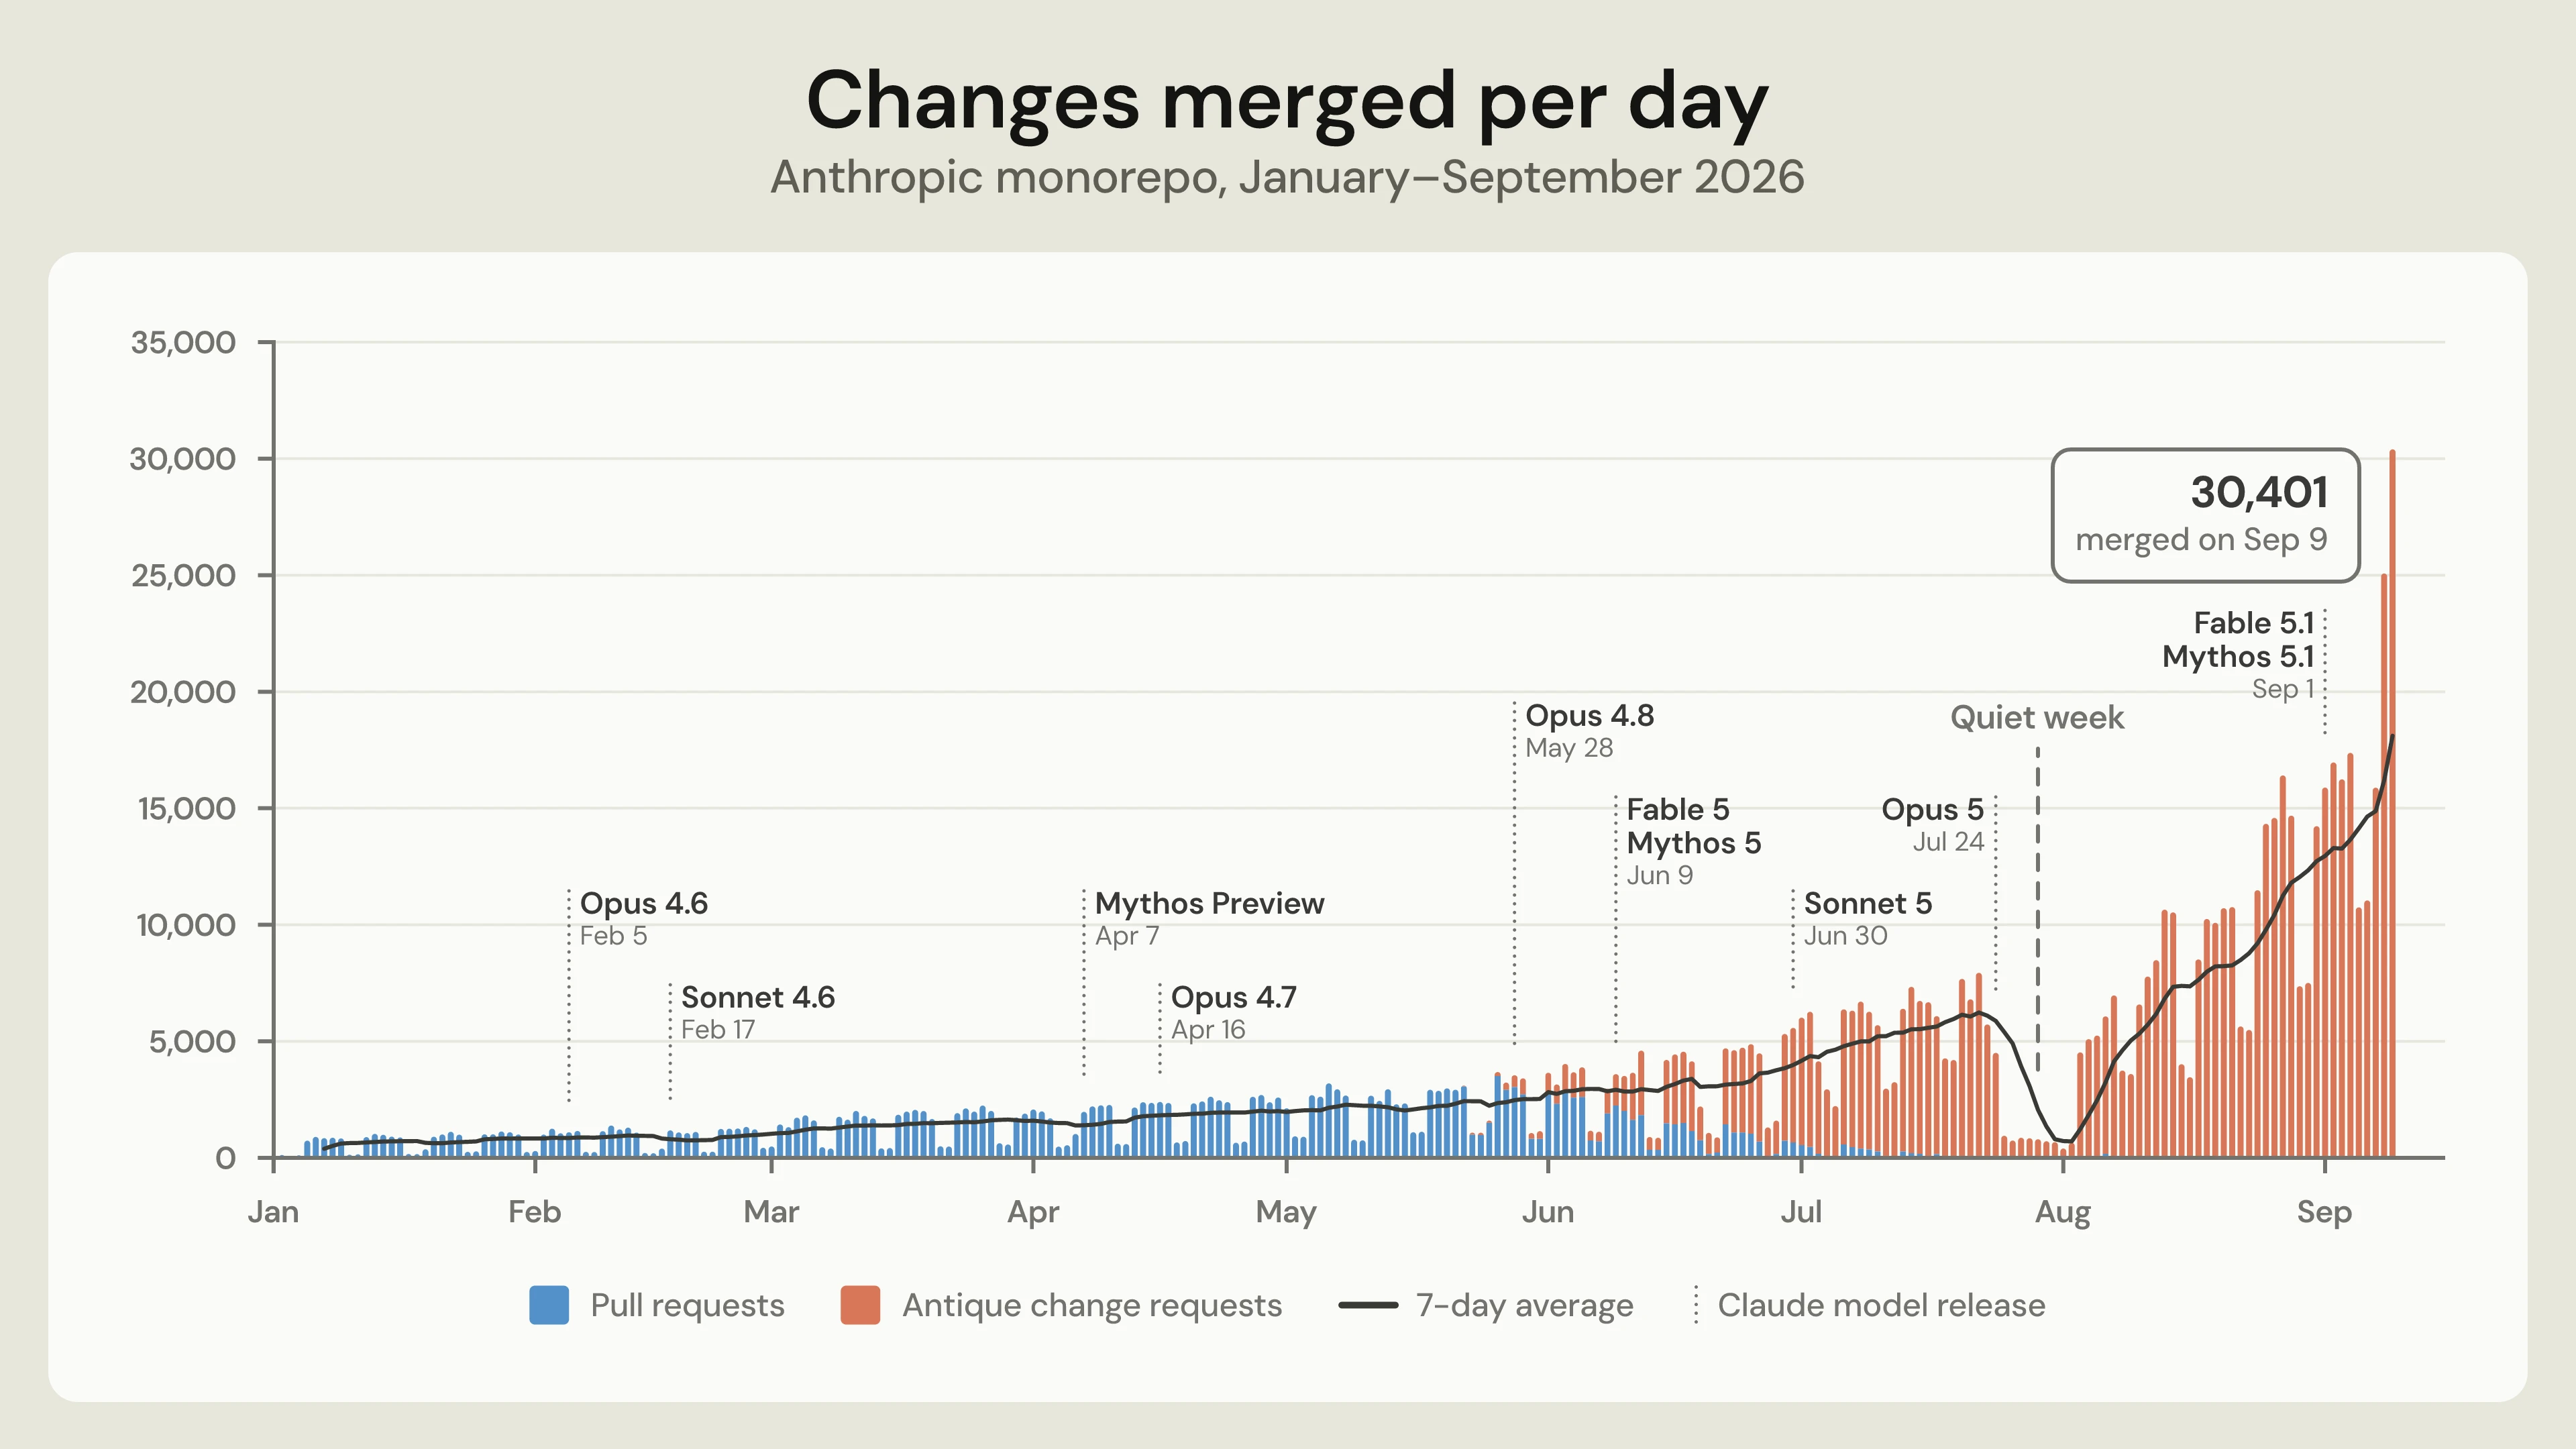
> as of September, we merged over 30,000 per day.

There's going to be an ugly phase where everybody FOMOs into thinking they need to do the same, only to realize that they're not Anthropic/Google/etc.

horsawlarway 4 hours ago||
I genuinely don't understand the core value they're pitching here. The tech is interesting, and I'm not trying to under cut that, but I question the idea that this is directionally valuable advice to nearly any company.

This amount of churn feels like a thing only possible with no real profit motives and a lot of money to waste.

Lots of activity is not necessarily synonymous with productivity, and it carries real cost.

So I think the design here is interesting, and the concepts seem applicable to where some agentic development may end up, but I question the underlying principles that drive this being the right solution space at all. At least if the goal is a profitable company.

eddythompson80 1 hour ago|||
Hysteria doesn't need to make sense. I think that's what OP is suggesting.

In the early/mid 2010s there was a similar hysteria about "deployments per day/week" metric. People were comparing products or teams by saying "My team deploys twice a week", "oh, yeah? we deploy 3 times a day". People viewed the north star of the CD part in CI/CD as pushing to production. The concept was simple, you push your code to main. CIs start churning, deploying it to test environments, then promoting it to staging, the pre-prod, then into blue/green prod deployment, then into prod. All automated, all touchless, happening on every merge, 5-10 times a day. That's engineering efficiency.

Many tried to follow that. It works great if your project is a Jekyll blog of course.

simianwords 4 hours ago|||
I think its pretty straightforward no? If agents are doing all of the work, they'd probably need to not have bottlenecks. This is going to be any company in the future, not just Anthropic. Wouldn't you agree.?
temac 3 hours ago|||
30000 a day seems already beyond absurd, it's one merge every 2.9s. I'm sure they will soon have more than one merge per second. From the graph, the rate was slightly lower but already insane as fuck the whole summer. An just regularly high to insane high sooner this year.

Yet IMO the admin controls Claude provides just started to be adequate for a small company a few weeks ago (and even so are still ridiculously fragmented and seem fragily designed and not exhaustively documented), so I can't even imagine for a big company.

Do you need that rate of change to make basic controls? I'm not sure. Do we see such dramatic fast evolution in the products? Not really. Are bugs we report actually fixed? I tried once and it just auto closed.

Anthropic should optimise for something more interesting than number of merges per second.

NoDodgeQuestion 4 hours ago|||
any company, merge 30,000 code changes per day? do not agree
winfredJa 4 hours ago||
im still not sure what they built software wise that warranted these many commits.
Robdel12 1 hour ago||
> As our monorepo grows, it increasingly doesn’t fit that design space. The history of our main branch alone is almost 100 GB, and a compressed working copy is over 25 GB. We perform on the order of 25 million code checkouts per day for CI, before counting developer environments, agent sandboxes, and research jobs. Fetched naively, that would be over 600 PB of git traffic per day.

I read this and wonder what their agents have committed into the repo that people aren't looking at for _that much size_? Do they have a ton of binary assets in there or something??

nickg-anthropic 48 minutes ago||
We have a file size limit of 5MB and I aggressively pruned all binary content that really wasn't fit for source control since it compresses really poorly and can cause performance problems in git when updating a checkout over many binary file changes.

This is really all just text.

grey-area 1 hour ago||
I suppose massive churn in commits would also bloat the history.

Not sure they should be proud of these numbers, they’re a sign of dysfunction.

altcognito 3 hours ago||
> 30k merges per day

> 25 million CI checkouts

833 checkouts for every merge? That's quite a few. Even accounting for multiple environments at different stages of production readiness, that's pretty weird.

nickg-anthropic 1 hour ago||
In a repo this large, there are a lot of tests and pipelines that need to run as code is tested, built, and deployed. Each test shard we run in parallel needs to check out the code, for example.
malfist 3 hours ago||
How about 100GB disk space for a checkout. That's pretty weird too. Makes you wonder if they're the best stewards for code. Makes you wonder about turning claude loose on your codebase.
xyzsparetimexyz 1 hour ago|||
The build directory for compiled code probably gets accidentally checked in and then removed 10 times a day.
altcognito 3 hours ago|||
I personally haven't dealt with a big-corp level of mono-repo. The choices you make might be justifiable to bring in certain binaries as opposed to resolve artifacts from some type of library repo. Especially if they are doing web front ends and whatnot?

And actually, the lack of an artifact server and some sort of proper knowledge of compatibility requiring a CI pull across hundreds of different projects with every merge is probably the explanation. Seems like there is an innovation waiting to happen there.

rhdunn 2 hours ago||
For local projects I'm using a repo per module/package, creating tagged releases, and pushing them to a local package hosting server. I can then reference those artifacts as dependencies in the projects that need/use them. No need for complex CI pulls, just coordinated releases.

I also have a template repository I use to help with common setup for different project types so I don't need to repeat that every time I create a new project.

For Python it's easy to create an artifact server as the artifacts are just wheel files in a directory with the server listing the directories (packages), files (releases), and downloading the files.

I'm not sure about other artifact servers for other projects.

Karrot_Kream 1 hour ago||
A bit thin on details, but seems like their solution presumes being always online, so rather than replicating a merkle tree it lets checkouts request source on demand. Is this "best practice" for large monorepos?
simonw 4 hours ago||
> In May 2026, Anthropic averaged around 2,500 code changes merged per day; as of September, we merged over 30,000 per day.

Here are the public model releases from Anthropic this year:

5th Feb 2026: Claude Opus 4.6

17th Feb 2026: Claude Sonnet 4.6

7th Apr 2026: Claude Mythos Preview

16th Apr 2026: Claude Opus 4.7

28th May 2026: Claude Opus 4.8

9th Jun 2026: Claude Fable 5

9th Jun 2026: Claude Mythos 5

30th Jun 2026: Claude Sonnet 5

24th Jul 2026: Claude Opus 5

1st Sep 2026: Claude Fable 5.1

1st Sep 2026: Claude Mythos 5.1

22nd Sep 2026: Claude Opus 5.5

28th Sep 2026: Claude Sonnet 5.5

7th Oct 2026: Claude Haiku 5.5

I would guess that any public model has been available internally for at least a month before that date, maybe longer.

My best guess is that the uptick in code changes corresponds to the availability of Mythos/Fable-class models inside of Anthropic.

simonw 14 minutes ago||
I had Claude recreate their chart from that article with these releases overlayed onto it: https://static.simonwillison.net/static/2026/anthropic-merge...
enraged_camel 4 hours ago||
>> My best guess is that the uptick in code changes corresponds to the availability of Mythos/Fable-class models inside of Anthropic.

Yeah. OpenAI basically said the same thing with regards to having Astra available to their team internally over the summer.

apf6 3 hours ago||
This is maybe a little less revolutionary than people are treating it? A lot of large tech companies (Google, Facebook, Microsoft) have already built their own homegrown SCM (or have implemented custom extensions to Git), because Git and other SCMs don't handle their scale. Most interesting thing about Scion is how quickly it was deployed.
DenisM 2 hours ago||
> Most interesting thing about Scion is how quickly it was deployed

Yes . And also they optimized for orders of magnitude more throughput and less latency, and fixing errors after the merge. This is new - they see enough benefit in velocity that justifies merging bugs and dealing with it later.

And it reminds me of when git came out and Linus said that git being super fast locally created a qualitative change in engineers head - it became a new way of working back then.

nickg-anthropic 2 hours ago||
Agreed! One of the main reasons we wanted to share this was that both the speed at which it was built and fully migrated onto and the "way" it was built are novel and show something about the kinds of things that are possible to build now.
mijoharas 5 hours ago||
So... Anthropic reinvents SVN?
bradfa 4 hours ago||
Feels more like perforce, but effectively, yes.
hejdenxi 4 hours ago||
[flagged]
simianwords 4 hours ago||
Anthorpic invanted new version control to do hype marketing and cash in the IPO before the bubble busrts (true story)
chris_money202 3 hours ago||
Why can't I rack my brain around why this is needed? I have had zero issues using git with agentic coding.
comboy 3 hours ago||
Neither can I. So they kept everything in a huge monorepo. Which unsurprisingly turned out to be problematic.

> Clients are always online. Git assumes that clients work offline and need a complete copy of the repository. Since nearly all of our clients are agents and jobs, we designed Scion’s client and protocols around a server that is always reachable, and have clients fetch data when they need it.

This also tells something about these companies idea of sandboxing.
bottlepalm 2 hours ago|||
30k commits per day indicates the agents are autonomous and not bounded by token limits. This system is probably barely keeping it on the rails as it is.
tasuki 2 hours ago||
It was not needed. It was just possible. I can see many ways for this to go wrong and am waiting eagerly with my popcorn.
mey 4 hours ago|
Did they reinvent subversion?
orangecat 3 hours ago||
Seems like it, and that's probably not a bad thing. Most companies have no need for git's distributed functionality, and even most open source projects just treat Github (or whatever) as the single source of truth.
tasuki 2 hours ago||
It is a terrible thing. Yes, one generally has a place which is the source of truth. But distributed still gives you offline commits and branching and all the good things, for free.
stigi 4 hours ago|||
I wanted to say, `scn` is waaaay to close to `svn`!
josephscott 3 hours ago|||
Reading through I was thinking the same thing, this reminds me a great deal of subversion.
hxugufjfjf 3 hours ago|||
That was my first thought lol
bsergean 4 hours ago||
[dead]
More comments...