Posted by yurivish 3 hours ago
If I had to do my individual tasks without AI, I would be slower. But if I take a step back, I'm really not changing the world any faster than I was before.
The other place they are amazing is in working with legacy code bases. I mean, the kind the dev team always wants to throw away. First, even if you do want to throw it away, you can first find out what it does and realize it does more than you think it does. You can also create integrations to more modern components which can be used to extend it. You can also create a pretty decent test suite if you do not have one. And, once the behaviour has good test coverage, you can re-write it into something more modern. You can even completely change the architecture while ensuring compatible external behaviour. Remember, this is all in place of “throw it away and start over from scratch, only to discover that the scope is much larger than expected”.
At work, they mostly let me increase quality, because it's easy to say find all parsers in my code base and fuzz them.
Of course, you can make a giant pile of doggy-doo-doo, but that was always true, just you can now make an epic Giza-sized pile.
Could you elaborate? What work are you doing which only exists because of AI?
I’m also required to explain how I use AI in my work. I must plan all of my future work, with an AI tool. Another AI assesses whether my work is aligning with planned work.
Before I work and after I work, there is a million circular references that exist solely because of AI. These have scaled because it’s so easy to do with AI, but the we’re wasting so much time doing a ton of extra things very efficiently.
Let me do my job. My manager should know how I’m doing. Maybe highlight key wins. CSATs/etc go out every year.
This sounds truly Kafkaesque. And thank you for finally allowing me to use that word in earnest.
Kafka and Byzantium had a baby.
It's not that deep—there were many more verticals outside of control plans, and there are now many more verticals outside of machine learning.
Or am I missing the point?
Anecdotally it seems like the majority of continued uplift comes from models doing more and exploring more of the search space, and we are getting better at giving them embarrassingly parallel problems to Hoover up with infinite token spend.
1. Intelligence per dollar spent/token output seems to be increasing rapidly. Opus 4 was $15/75 per million input/output tokens when released. Opus 5.5, which is significantly better, is $4/15. Sure it cost more money upfront to train Opus 5.5, or the bigger model (Fable 5.5) which tuned it, but once it is reached, there are massive diffusive effects.
2. The capital equation is still favoring more spend. Anthropic's revenue is growing rapidly and they are profitable on inference. Huge upfront spend for realized gains later on is standard for R&D. As long as serving the models is profitable and generates more value than the energy/compute consumed
3. The search space is too large to assume that improvement in AI assisted research is just models dumbly trying every combination until something works. For every additional bit searched, the space doubles, so even a trivially small combinatorial exploration incurs prohibitively large costs. Intelligent searching which continuously prunes that space along dimensions of effectiveness is not a trivial skill and is among the emergent accoutrements of these smarter models.
But they are essentially fighting for smaller and smaller part of the pie. The better open models are the less you need frontier models, so the frontier AI companies are essentially fighting for market that will shrink the better AI is.
Sure there is inertia and the usual corporate enterprise nonsense of "we only buy stuff from other big companies regardless the cost" that keeps the licenses going but we're quickly getting into point where you don't need any of the frontier models to do majority of the tasks
I mainly think this because frontier labs already try to compete at this tier. For example, 6.1 Sol has identical pricing to Kimi K3.1, but with a lower price per task due to Kimi's verbosity. It seems to score roughly the same on most benchmarks, with some (like Artificial Analysis) putting 6.1 Sol significantly higher. If you need to step down, 6.1 Terra is also cheaper than K3.1 or K3 and performs well relative to their benchmarks. Opus 5.5 and much of Anthropic's recent push seems to confirm this as a major area of focus as well.
I still use a lot of open models and harnesses, but I don't know if cost competitiveness (at least not with the current crop of open models) will ultimately drive a huge chunk of average users away.
Things could change, but fundamentally, large labs aren't precluded from training more cost effective models if there is significant demand for them, which is what we're seeing now.
6.1 Sol is not a “frontier model” and does not command the pricing of one. The reason it exists is because of competition from non-frontier models that are “good enough”.
In fact, you kind of made the same argument. As “good enough” models commoditized, the use cases requiring frontier models and frontier model pricing will shrink.
And, even if performance is not as good, many will prefer open models.
True in theory, but in practice hardware availability and cost will keep open source impractical for years to come.
I would also like to point out that “profitable on inference” is similarly meaningless, because it’s based on a figure that arbitrarily discards whatever bits of their operating costs they need to to get to the claim that they’re profitable on inference. Potentially including ones that can’t be ignored because they’re every bit as much a part of COGS as the actual inference is.
It's going to depend on the task (and this is prone to cheating), but you can get a decent idea by looking at task benchmarks and the cost of completing them.
I was inclined to agree but Anthropic's latest S-1 statement only includes a paper loss due to their value going up. They're objectively making money now, the only question is can they keep it up and can they grow enough to be able to pay the bills they've signed up for in future?
Which is a really important distinction. One measures specific points on the jagged boundary. The other is a word that blithely paints it all with a single brush, and sweeps the jagged boundary problem under the rug in the process.
It really is important to keep track of that. Whenever we talk about “intelligence” as if it were a well-defined (let alone quantifiable) thing, we fall into the kind of wooly thinking that lets anyone say pretty much anything. We abandon the realm of grounded statements in favor of pure vibes.
What information are you trying to either ask for or share with us?
The original article is pretty clear, agent swarms and token spend are AI automating AI, and the RSP attribution condition specifically excludes your capital thrown at training concern?
Not at all. Have you tried local AI lately? Qwen 3.8 is legitimately much better than SoTA from 1 year ago (Opus 4.1). You can run it on a consumer GPU.
Qwen Next Flash runs on a DGX spark well and is as good as some things you need datacenter class GPU's to run even today.
Check out Artificial Analysis if you haven't. Sometimes you don't realize how fast these things are moving, but to compare things from a year ago to today is just wild.
They aren't just getting better, they're getting more efficient by many orders of magnitude.
I'm not sure I follow. Are you saying a hardware shortage is going to restrict AI development? Because it seems to me like it would just push us towards an even greater focus on efficiency, which is still pushing the Pareto Frontier.
But, then as now, what they didn’t have was profits.
But that didn’t stop the AI winter from coming. Because a technology being transformative does not protect it from over-investment. History perhaps suggests the opposite is true.
Nor did it prevent the AI companies of the 80s from going bankrupt when they got undercut by the commoditization that naturally came with the maturation of the technology.
We're coming up on four years since ChatGPT launched, and the only thing LLMs seem to excel at is the movement of imaginary little green pieces of paper.
We're getting the Claude efficiency talks at work. We're looking at all sort of optimizations, including local models and graphify, to reduce spend. There are people dedicating their nights and weekends to dropping token consumption and cache rebuilding. A few of these will likely catch on and be brought into common use. That will relieve at least a bit of the pressure, and enable some of the scaling to continue.
the same thing you are:
> if I may ask?
asking.
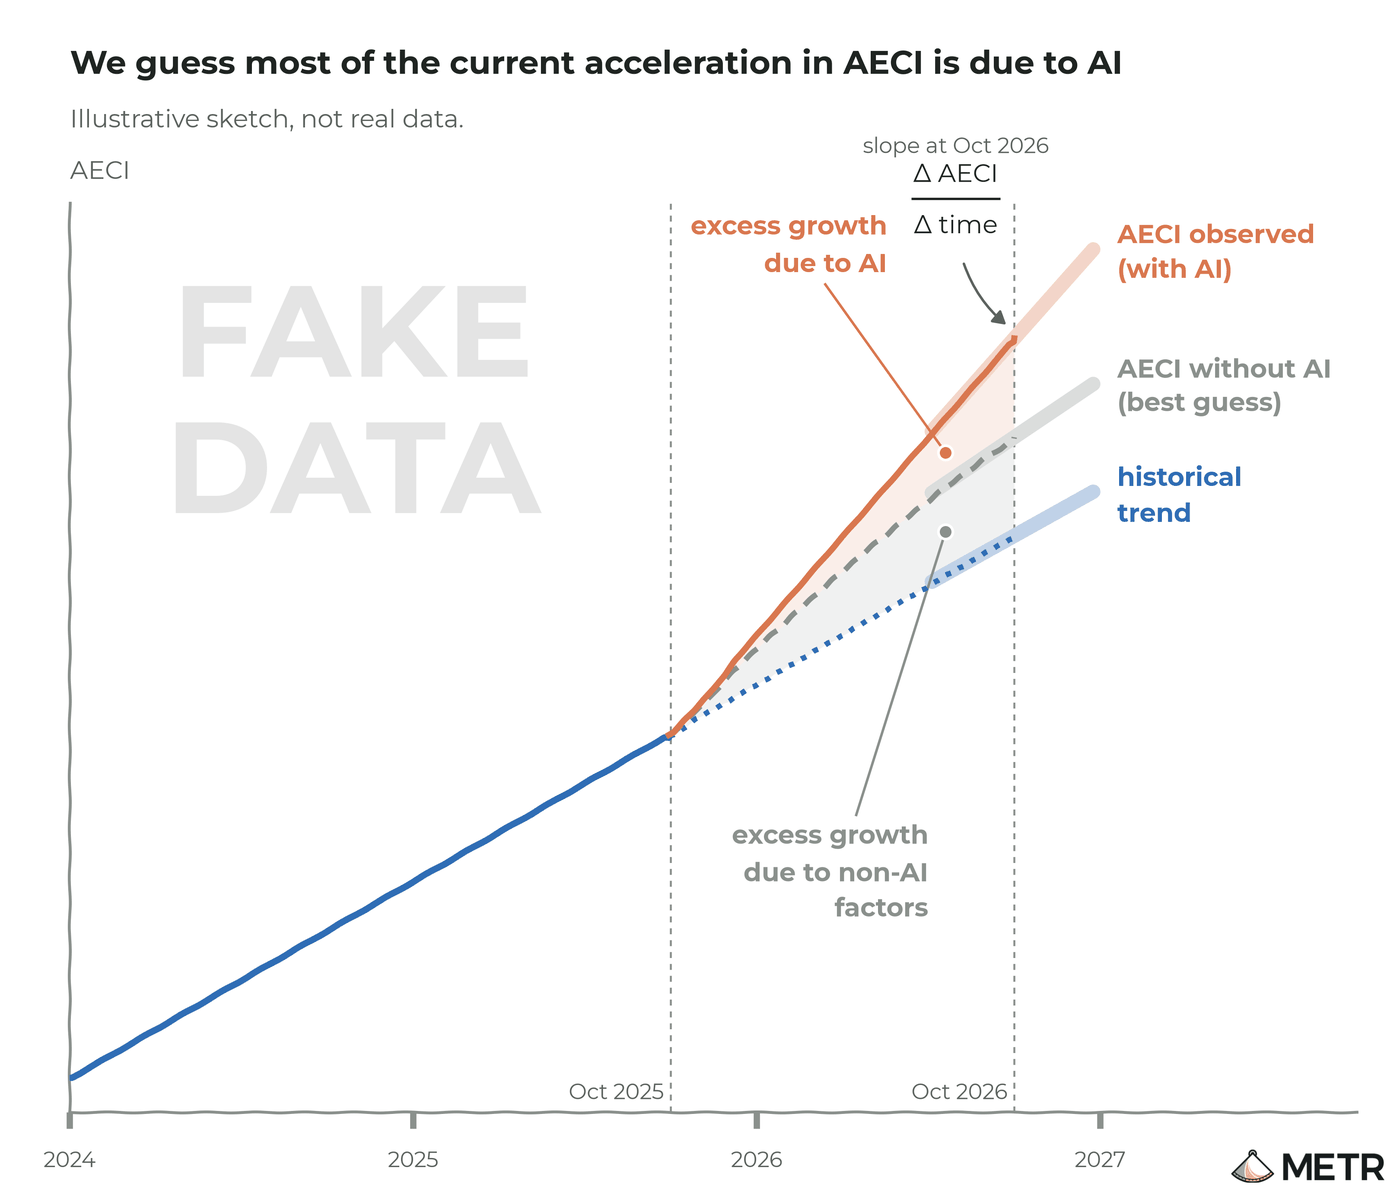
The ECI is basically an aggregate of benchmark scores, but benchmark complexity might not increase linearly. In fact, if LLM capabilities grew exponentially, then new benchmarks would also need to increase their difficulty / complexity exponentially to stay unsaturated and relevant.
In the original article he noted that getting to a 2x increase in capabilities would be crazy and require ~40x researcher productivity; that’s exactly the increase the new data now shows, and thus a huge number of the assumptions made in this earlier post about how it’s unlikely we would get to this point have literally already been proven wrong less than two months later.
I expect to see an update from Ramez moving substantially more in the direction of RSI in fact very much increasing the odds of reaching ASI soon.
Given that frontier models are leapfrogging and massive infrastructure buildouts are ongoing, I don’t see why any of these three couldn’t be overcome.
Side note: I’m also curious why people (myself included) don’t seem to be getting much more intelligent as AI becomes widely available. As if humans are bounded to the earth, while AI is leaping for Mars.
This combined with ability to massively scale experiments for even (or maybe particularly) the most mundane performance tweaks might just be making the process of improving AI more efficient.
On the other hand I still only get meaningless blabla when I let them write s.th. without telling what is important.
That is, unless this is saying that automated AI research is going to get us to "smarter models with fewer parameters" and of course, these are faster to train, then I can see how the exponential loop really gets going, but there's certainly an information theoretical limit here?
Getting past this bottleneck is gonna mean training our models not in datacenters, but in places that more closely resemble the ones where we want them to act. A factory, a wet lab, outer space... imagine a million robots spending all day finding every way to fall off the monkey bars so that the next version doesn't.
Im not telling it what to do, i ask it for ar eport/analysis and research and read its article and tell it what to implement based on 'feelings' and it works.
Limit is hardware and tokens and an AI Researcher not having hardware or tokens is probably not what they refer to.
Alone normal researchers were quite handicaped: converting data from tool a to python library x, understanding how tools work, doing basic google research etc.
On a more fun note, I also find just trying some hair brained idea is now extremely cheap - so why not? I used to have to weigh up spending a week of effort on something likely not to work and now I can now get spit out test in 20 minutes.
The agent then works for 20 minutes and comes back with, "Yes this is a problem. Here is the evidence. Here is a golden data set. Finally I built a new evaluation metric and benchmark where we can back test or use for new model experiments to see if we are closing the gap."
I always wanted to build a specific event/sequence in one LSD trip into a small game to give that experience some kind of playability.
Then I saw some 4k demo, wanted to see how good it is in doing this.
Its really fun yeah :)
I read it about 20 years ago, and once it got into nanobots and Kurzweil's vision that the whole universe would be intelligent, I didn't find the book credible.
But I'm wondering if the short-term prediction, that in the 2030s we won't be able to anticipate what tech does for us, (IE, the Singularity,) is useful?
Even if he turns out to be a decade or two off, that’s basically exactly correct in the sweep of history sense.
Wild time to be alive.
https://metr.org/assets/images/ai-rd-acceleration-assessment...
Mathematicians for example have used it as cope for their current reliance on unsavory corporations, telling themselves "just one more year, and I can solve a millennium problem on my Asus Strix".